Page: 1
/ 14
Total 231 questions
Databricks Certified Data Engineer Associate Exam Questions
Question 1
A company has a strict 15-minute service-level agreement for updating its currency-exchange dashboard. Source data arrives in small increments every few minutes. The team needs a Lakeflow Jobs trigger strategy that keeps end-to-end latency within the SLA while minimizing compute cost and DBU consumption.
Which strategy is recommended?
Answer : D
Question 2
A data engineer needs to ingest from both streaming and batch sources for a firm that relies on highly accurate dat
a. Occasionally, some of the data picked up by the sensors that provide a streaming input are outside the expected parameters. If this occurs, the data must be dropped, but the stream should not fail.
Which feature of Delta Live Tables meets this requirement?
Answer : D
Question 3
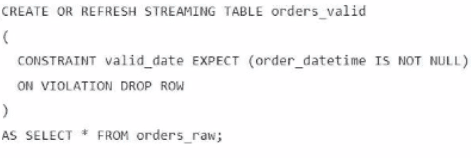
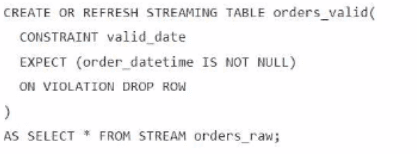
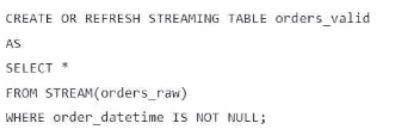
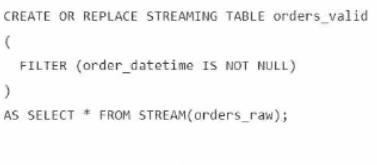
A data engineer is processing ingested streaming tables and needs to filter out NULL values in the order_datetime column from the raw streaming table orders_raw and store the results in a new table orders_valid using DLT.
Which code snippet should the data engineer use?
A)
B)
C)
D)
Answer : C
Question 4
A data engineer needs to migrate the Unity Catalog external Delta table catalog.schema.sales while meeting the following requirements:
Databricks must manage file cleanup after the table is dropped.
The migration must minimize downtime while retaining the same table name, permissions, and history.
Access must be enforced through the registered Unity Catalog table name.
Which action should the engineer take?
Answer : A
Question 5
An organization has data stored across multiple external systems, including MySQL, Amazon Redshift, and Google BigQuery. The data engineer wants to perform analytics without ingesting data directly into Databricks, while ensuring unified governance and minimizing data duplication.
Which feature of Databricks enables querying these external data sources while maintaining centralized governance?
Answer : A
Lakehouse Federation is the Databricks feature built for querying external systems without moving all data into Databricks. Databricks documentation describes it as the platform for query federation, enabling users to run queries against multiple external data sources while keeping governance centralized through Unity Catalog. Databricks also documents support for external systems such as Amazon Redshift and other databases through connections and foreign catalogs, allowing read-only access to external data while managing permissions in Unity Catalog. This aligns directly with the requirement to minimize duplication and still maintain centralized governance. Databricks Connect is for local development against Databricks compute, not federated querying. MLflow is for machine learning lifecycle management. Delta Lake is a storage format and table layer, not a federation framework. Therefore, when the goal is unified governance across Databricks and external systems like MySQL, Redshift, and BigQuery without first ingesting the data, Lakehouse Federation is the documented answer. Databricks does note that for high-volume production ingestion, managed connectors may sometimes be preferred, but for direct querying without data movement, Lakehouse Federation is the correct feature.
Question 6
A data engineer is building a nightly batch ETL pipeline that processes very large volumes of raw JSON logs from a data lake into Delta tables for reporting. The data arrives in bulk once per day, and the pipeline takes several hours to complete. Cost efficiency is important, but performance and reliable completion of the pipeline are the highest priorities.
Which type of Databricks cluster should the data engineer configure?
Answer : A
For large-scale batch ETL workloads, Databricks documentation recommends using job clusters that are created specifically for a job run and terminated automatically when the job completes. A job cluster with autoscaling enabled provides the best balance of performance, reliability, and cost efficiency for long-running nightly pipelines. Autoscaling allows the cluster to dynamically add or remove worker nodes based on the workload demands, ensuring sufficient parallelism to process very large JSON datasets efficiently while avoiding overprovisioning when demand decreases. This is especially important when processing raw data into Delta tables, where shuffle-heavy transformations and writes benefit from multiple workers. Single-node clusters (option B) are not suitable for very large volumes of data and risk excessive runtimes or job failures. High-concurrency clusters (option C) are optimized for interactive and concurrent SQL queries, not long-running batch ETL jobs. Always-on all-purpose clusters (option D) increase costs unnecessarily and are intended for interactive development, not scheduled production pipelines. Databricks best practices clearly position autoscaling job clusters as the preferred solution for reliable, cost-effective batch ETL in production on Databricks.
Question 7
A new data engineering team team has been assigned to an ELT project. The new data engineering team will need full privileges on the table sales to fully manage the project.
Which of the following commands can be used to grant full permissions on the database to the new data engineering team?
Answer : A
To grant full permissions on a table to a user or a group, you can use theGRANT ALL PRIVILEGES ON TABLEstatement. This statement will grant all the possible privileges on the table, such asSELECT,CREATE,MODIFY,DROP,ALTER, etc. Option A is the only code block that follows this syntax correctly. Option B is incorrect, as it does not grant all the possible privileges on the table, but only a subset of them. Option C is incorrect, as it only grants theSELECTprivilege on the table, which is not enough to fully manage the project. Option D is incorrect, as it grants theUSAGEprivilege on the table, which is not a valid privilege for tables. Option E is incorrect, as it grants all the privileges on the tableteamto the user or groupsales, which is the opposite of what the question asks.Reference:Grant privileges on a table using SQL | Databricks on AWS,Grant privileges on a table using SQL - Azure Databricks,SQL Privileges - Databricks
 All Official Question Types