Page: 1
/ 14
Total 215 questions
Databricks Certified Data Engineer Professional Exam Questions
Question 1
A data engineering team uses Databricks Lakehouse Monitoring to track the percent_null metric for a critical column in their Delta table.
The profile metrics table (prod_catalog.prod_schema.customer_data_profile_metrics) stores hourly percent_null values.
The team wants to:
Trigger an alert when the daily average of percent_null exceeds 5% for three consecutive days.
Ensure that notifications are not spammed during sustained issues.
Options:
Answer : B
The key requirement is to detect when the daily average of percent_null is greater than 5% for three consecutive days.
Option A only checks the last 24 hours, not consecutive days. It would trigger too frequently and cause spam.
Option C calculates an average across all records in the last 3 days, but this could be skewed by one high or low day --- it does not ensure consecutive daily violations.
Option D simply counts days where the threshold was exceeded, but it does not guarantee that those days were consecutive. This could incorrectly trigger on non-adjacent violations.
Option B is correct:
It aggregates hourly values into daily averages.
It checks that the last 3 consecutive days all had averages above 5%.
It avoids redundant alerts by using Notification Frequency: Just once.
This matches Databricks Lakehouse Monitoring best practices, where SQL alerts should be designed to aggregate metrics to the correct granularity (daily here) and ensure consecutive threshold violations before triggering.
Reference (Databricks Lakehouse Monitoring, SQL Alerts Best Practices):
Use DATE_TRUNC to compute metrics at the correct time granularity.
To detect consecutive-day issues, filter the last N daily aggregates and check conditions across all rows.
Always configure alerts with controlled notification frequency to prevent alert fatigue.
Question 2
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.
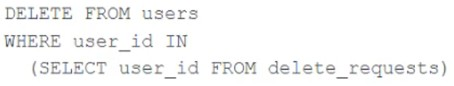
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Answer : E
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage. Verified Reference: [Databricks Certified Data Engineer Professional], under ''Delta Lake'' section; Databricks Documentation, under ''Delete from a table'' section; Databricks Documentation, under ''Remove files no longer referenced by a Delta table'' section.
Question 3
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer : B
Apache Spark documents DataFrame.transform(func, *args, **kwargs) as concise syntax for chaining custom transformations, where the function takes a DataFrame and returns a DataFrame. The official example explicitly shows chained transforms, which makes option B the most modular and idiomatic ETL design among the choices. (Apache Spark)
Option D shows a valid single transform and test, but it does not demonstrate the modular pipeline composition aspect as clearly as B. Option A does not actually use DataFrame.transform, and option C wraps logic in a class method but does not demonstrate the documented chaining pattern that transform is designed for. (Apache Spark)
======
Question 4
The data engineering team has configured a job to process customer requests to be forgotten (have their data deleted). All user data that needs to be deleted is stored in Delta Lake tables using default table settings.
The team has decided to process all deletions from the previous week as a batch job at 1am each Sunday. The total duration of this job is less than one hour. Every Monday at 3am, a batch job executes a series of VACUUM commands on all Delta Lake tables throughout the organization.
The compliance officer has recently learned about Delta Lake's time travel functionality. They are concerned that this might allow continued access to deleted data.
Assuming all delete logic is correctly implemented, which statement correctly addresses this concern?
Answer : E
https://learn.microsoft.com/en-us/azure/databricks/delta/vacuum
Question 5
A platform team lead is responsible for automating SQL Warehouse usage attribution across business units. They need to identify warehouse usage at the individual user level and share a daily usage report with an executive team that includes business leaders from multiple departments.
How should the platform lead generate an automated report that can be shared daily?
Answer : B
Databricks provides system tables under the system.billing and system.access schemas for auditing and cost attribution across SQL Warehouses. The best practice is to build a dashboard in Databricks SQL using these system tables and configure it with a daily refresh schedule. This ensures automated, up-to-date reporting of compute consumption, user activity, and cost distribution. Sharing this dashboard with executives provides transparency without requiring them to run queries manually. This approach aligns with Databricks' operational guidance on workspace observability and cost governance, making B the correct answer.
Question 6
Which Python variable contains a list of directories to be searched when trying to locate required modules?
Answer : B
Question 7
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
Personally Identifiable Information (PII) such as email, phone number, and IP address must be masked or anonymized before storage.
Both batch and streaming pipelines must apply consistent PII handling.
Masking logic must be auditable and reproducible.
The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
Answer : D
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
 All Official Question Types