Page: 1
/ 14
Total 106 questions
Google Cloud Associate Data Practitioner Exam Questions
Question 1
Your company has an on-premises file server with 5 TB of data that needs to be migrated to Google Cloud. The network operations team has mandated that you can only use up to 250 Mbps of the total available bandwidth for the migration. You need to perform an online migration to Cloud Storage. What should you do?
Answer : A
Comprehensive and Detailed in Depth
Why A is correct:Storage Transfer Service with agent-based transfer allows for online migrations and provides the ability to set bandwidth limits.
Agents are installed on-premises and can be configured to respect network constraints.
Why other options are incorrect:B: The --daisy-chain option is not related to bandwidth control.
C: Transfer Appliance is for offline migrations and is not suitable for online transfers with bandwidth constraints.
D: The --no-clobber option prevents overwriting existing files but does not control bandwidth.
Storage Transfer Service: https://cloud.google.com/storage-transfer-service/docs
Storage Transfer Service Agents: https://cloud.google.com/storage-transfer-service/docs/agent-overview
gcloud storage cp: https://cloud.google.com/storage/docs/gsutil/commands/cp
Question 2
Your data science team needs to collaboratively analyze a 25 TB BigQuery dataset to support the development of a machine learning model. You want to use Colab Enterprise notebooks while ensuring efficient data access and minimizing cost. What should you do?
Answer : B
Comprehensive and Detailed In-Depth
For a 25 TB dataset, efficiency and cost require minimizing data movement and leveraging BigQuery's scalability within Colab Enterprise.
Option A: Exporting 25 TB to Google Drive and loading via Pandas is impractical (size limits, transfer costs) and slow.
Option B: BigQuery magic commands (%%bigquery) in Colab Enterprise allow direct querying of BigQuery data, keeping processing in the cloud, reducing costs, and enabling collaboration.
Option C: Dataproc with Spark adds cluster costs and complexity, unnecessary when BigQuery can handle the workload.
Option D: Copying 25 TB to local storage is infeasible due to size and cost. Extract from Google Documentation: From 'Using BigQuery with Colab Enterprise' (https://cloud.google.com/colab/docs/bigquery): 'You can use BigQuery magic commands (%%bigquery) in Colab Enterprise to execute SQL queries directly against BigQuery datasets, providing efficient access to large-scale data without moving it.' Reference: Google Cloud Documentation - 'Colab Enterprise with BigQuery' (https://cloud.google.com/colab/docs).
Extract from Google Documentation: From 'Using BigQuery with Colab Enterprise' (https://cloud.google.com/colab/docs/bigquery): 'You can use BigQuery magic commands (%%bigquery) in Colab Enterprise to execute SQL queries directly against BigQuery datasets, providing efficient access to large-scale data without moving it.'
Option D: Copying 25 TB to local storage is infeasible due to size and cost. Extract from Google Documentation: From 'Using BigQuery with Colab Enterprise' (https://cloud.google.com/colab/docs/bigquery): 'You can use BigQuery magic commands (%%bigquery) in Colab Enterprise to execute SQL queries directly against BigQuery datasets, providing efficient access to large-scale data without moving it.' Reference: Google Cloud Documentation - 'Colab Enterprise with BigQuery' (https://cloud.google.com/colab/docs).
Question 3
You work for a financial services company that handles highly sensitive dat
a. Due to regulatory requirements, your company is required to have complete and manual control of data encryption. Which type of keys should you recommend to use for data storage?
Answer : A
For regulatory requirements that mandate complete and manual control of data encryption, you should use customer-supplied encryption keys (CSEK). With CSEK, your company provides the encryption keys for data storage, and Google Cloud does not store or manage these keys. This approach ensures that your organization retains full control and responsibility over the encryption process, meeting strict regulatory compliance requirements.
Question 4
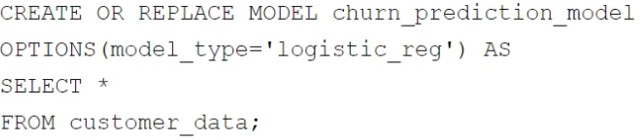
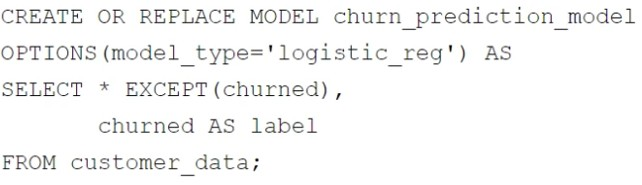
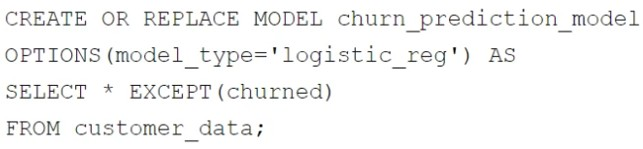
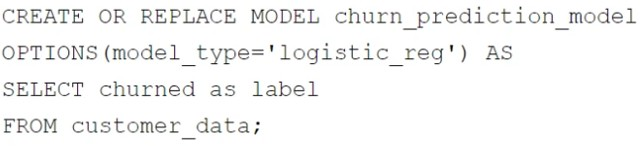
Your retail company wants to predict customer churn using historical purchase data stored in BigQuery. The dataset includes customer demographics, purchase history, and a label indicating whether the customer churned or not. You want to build a machine learning model to identify customers at risk of churning. You need to create and train a logistic regression model for predicting customer churn, using the customer_data table with the churned column as the target label. Which BigQuery ML query should you use?
A)
B)
C)
D)
Answer : B
In BigQuery ML, when creating a logistic regression model to predict customer churn, the correct query should:
Exclude the target label column (in this case, churned) from the feature columns, as it is used for training and not as a feature input.
Rename the target label column to label, as BigQuery ML requires the target column to be named label.
The chosen query satisfies these requirements:
SELECT * EXCEPT(churned), churned AS label: Excludes churned from features and renames it to label.
The OPTIONS(model_type='logistic_reg') specifies that a logistic regression model is being trained.
This setup ensures the model is correctly trained using the features in the dataset while targeting the churned column for predictions.
Question 5
You are storing data in Cloud Storage for a machine learning project. The data is frequently accessed during the model training phase, minimally accessed after 30 days, and unlikely to be accessed after 90 days. You need to choose the appropriate storage class for the different stages of the project to minimize cost. What should you do?
Answer : B
Comprehensive and Detailed In-Depth
Cost minimization requires matching storage classes to access patterns using lifecycle rules. Let's assess:
Option A: Nearline during training (frequent access) incurs high retrieval costs and latency, unsuitable for ML workloads. Coldline after 30 days and Archive after 90 days are reasonable but misaligned initially.
Option B: Standard storage (no retrieval fees, low latency) is ideal for frequent access during training. Transitioning to Nearline (30-day minimum, low access) after 30 days and Coldline (90-day minimum, rare access) after 90 days matches the pattern and minimizes costs effectively.
Option C: Nearline during training is costly for frequent access, and Archive to Coldline is illogical (Archive is cheaper than Coldline).
Option D: DRA storage doesn't exist in Google Cloud (legacy AWS term); the progression should be Standard -> Nearline -> Coldline. Why B is Best: Standard ensures training efficiency, while Nearline and Coldline reduce costs as access drops, all manageable via lifecycle rules (e.g., SetStorageClass actions). This is Google's recommended tiering strategy. Extract from Google Documentation: From 'Cloud Storage Classes' (https://cloud.google.com/storage/docs/storage-classes): 'Use Standard storage for frequently accessed data, such as during active ML training. Transition to Nearline after 30 days for infrequent access, and Coldline after 90 days for rare access, optimizing costs with lifecycle management.' Reference: Google Cloud Documentation - 'Storage Classes' (https://cloud.google.com/storage/docs/storage-classes).
Why B is Best: Standard ensures training efficiency, while Nearline and Coldline reduce costs as access drops, all manageable via lifecycle rules (e.g., SetStorageClass actions). This is Google's recommended tiering strategy.
Extract from Google Documentation: From 'Cloud Storage Classes' (https://cloud.google.com/storage/docs/storage-classes): 'Use Standard storage for frequently accessed data, such as during active ML training. Transition to Nearline after 30 days for infrequent access, and Coldline after 90 days for rare access, optimizing costs with lifecycle management.'
Option D: DRA storage doesn't exist in Google Cloud (legacy AWS term); the progression should be Standard -> Nearline -> Coldline. Why B is Best: Standard ensures training efficiency, while Nearline and Coldline reduce costs as access drops, all manageable via lifecycle rules (e.g., SetStorageClass actions). This is Google's recommended tiering strategy. Extract from Google Documentation: From 'Cloud Storage Classes' (https://cloud.google.com/storage/docs/storage-classes): 'Use Standard storage for frequently accessed data, such as during active ML training. Transition to Nearline after 30 days for infrequent access, and Coldline after 90 days for rare access, optimizing costs with lifecycle management.' Reference: Google Cloud Documentation - 'Storage Classes' (https://cloud.google.com/storage/docs/storage-classes).
Question 6
You want to process and load a daily sales CSV file stored in Cloud Storage into BigQuery for downstream reporting. You need to quickly build a scalable data pipeline that transforms the data while providing insights into data quality issues. What should you do?
Answer : A
Using Cloud Data Fusion to create a batch pipeline with a Cloud Storage source and a BigQuery sink is the best solution because:
Scalability: Cloud Data Fusion is a scalable, fully managed data integration service.
Data transformation: It provides a visual interface to design pipelines, enabling quick transformation of data.
Data quality insights: Cloud Data Fusion includes built-in tools for monitoring and addressing data quality issues during the pipeline creation and execution process.
Question 7
You are working with a large dataset of customer reviews stored in Cloud Storage. The dataset contains several inconsistencies, such as missing values, incorrect data types, and duplicate entries. You need to clean the data to ensure that it is accurate and consistent before using it for analysis. What should you do?
Answer : B
Using BigQuery to batch load the data and perform cleaning and analysis with SQL is the best approach for this scenario. BigQuery provides powerful SQL capabilities to handle missing values, enforce correct data types, and remove duplicates efficiently. This method simplifies the pipeline by leveraging BigQuery's built-in processing power for both cleaning and analysis, reducing the need for additional tools or services and minimizing complexity.
 All Official Question Types