Page: 1
/ 14
Total 50 questions
HP Advanced HPE Storage Integrator Solutions Written HPE7-J02 Exam Questions
Question 1
The storage solution based on the exhibit is deployed at a customer site.
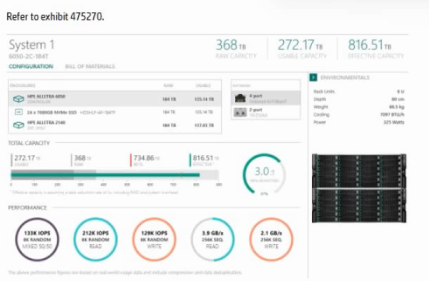
How can the sequential read performance values be enhanced for this configuration?
Answer : B
Detailed Explanatio n:
Rationale for Correct Answe r:
The exhibit shows a system delivering ~2.3 GB/s sequential read. For large-block sequential workloads, aggregate host link bandwidth (number speed of front-end ports) is the primary limiter. Increasing the count of 10/25 Gb iSCSI NICs adds parallel lanes, raising sustained read GB/s to the hosts. This is a recommended first step in HPE sizing before changing protocols.
Analysis of Incorrect Options (Distractors):
A: Adding an expansion shelf increases capacity, not front-end bandwidth.
C: Moving to 32 Gb FC can help, but simply adding more existing 10/25 Gb ports achieves the same goal without a protocol/adapter change and is the straightforward, supported scale-out path.
D: SCM (Storage Class Memory) targets latency/IOPS; it doesn't materially lift sequential GB/s if the link budget is the bottleneck.
Key Concept: Scale front-end connectivity to increase sequential throughput; capacity or media class changes won't fix a link-limited system.
Question 2
You are sizing an HPE Alletra 5030. Unless otherwise indicated by the HPE sizer or the customer's requirements, HPE best practices state that you should default to which minimum FDR calculation?
Answer : A
Detailed Explanatio n:
Rationale for Correct Answe r:
In Alletra 5000/6000 sizing, the Failure Domain Reserve (FDR) is used to account for rebuild overhead in case of drive failure. HPE best practices define that, unless otherwise directed by the sizing tool or customer requirements, the minimum FDR value should be set to 23% of the largest drive size. This ensures enough reserve capacity for fault tolerance and sustained performance during rebuilds.
Distractors:
B/C: Low-read latency is influenced by cache and workload profile, not by arbitrary FDR percentages.
D: Using the smallest drive is incorrect --- rebuild impact must be sized against the largest drive.
Key Concept: FDR sizing based on 23% of largest drive = HPE best practice.
Question 3
Your new customer asks about HPE storage networking capabilities for multisite implementations.
Which statement about HPE's FCIP capabilities is correct?
Answer : A
Detailed Explanatio n:
Rationale for Correct Answe r:
In Brocade (HPE B-Series) SAN switches, FCIP trunking allows multiple IP circuits to be aggregated. This increases bandwidth and provides resiliency (if one link fails, traffic continues over remaining paths). It is the correct statement regarding HPE's FCIP feature set.
Distractors:
B: High availability still requires redundant fabrics; FCIP trunking alone doesn't replace fabric design best practices.
C: FCIP can run over shared IP WANs; no need for dedicated links.
D: Encryption adds overhead; performance impact exists (although minimal with hardware offload).
Key Concept: FCIP trunking = bandwidth + availability for multisite SAN.
Question 4
You need to evaluate a customer's virtual server environment to size an HCI solution based on HPE SimpliVity according to usage metrics over time. The environment consists of Dell servers and storage running VMware virtualization.
Which action can you use to gather the usage metrics of this setup?
Answer : C
Detailed Explanatio n:
Rationale for Correct Answe r:
For competitive or 3rd-party (non-HPE) environments like Dell + VMware, HPE CloudPhysics is the correct tool. The Observer VM is deployed into vCenter to gather real-world workload metrics (CPU, memory, storage I/O). These analytics can then be used for SimpliVity HCI sizing.
Distractors:
A: NinjaOnline SimpliVity Sizer requires input metrics, but it cannot directly collect from 3rd-party environments.
B: InfoSight sizing applies to HPE arrays, not competitive storage.
D: InfoSight for SimpliVity only monitors existing HPE SimpliVity clusters.
Key Concept: CloudPhysics Observer gathers competitive workload metrics feeds into SimpliVity sizing.
Question 5
Your customer is deploying HPE Morpheus Enterprise Software as a single orchestration platform for compute and storage resources. To achieve a high-availability deployment in a single site, how many VMs must be deployed if distributed databases are not required?
Answer : C
Detailed Explanatio n:
Rationale for Correct Answe r:
HPE Morpheus can run as a single VM in non-critical environments, but for high availability (HA) without distributed databases, the recommendation is to deploy 3 VMs in a cluster. This ensures quorum and redundancy across application nodes, protecting against single VM failure. Distributed database mode requires more VMs, but is not needed in this scenario.
Distractors:
A: 4 VMs are required only if distributed DB is enabled (PostgreSQL cluster), not here.
B/D: A single VM (with or without VMware HA) doesn't provide native Morpheus HA resilience.
Key Concept: Morpheus HA = 3-node cluster minimum without distributed DB.
Question 6
Your customer has deployed an HPE Alletra MP B10000 array in its virtualized environment. Data protection follows 3-2-1 best practices, with snapshots on the array, Veeam v12 backups, and storage on an external HPE StoreOnce appliance. Despite this, a ransomware attack made data recovery impossible.
Your customer asks how to enhance data protection with immutability and application consistency.
What is a possible solution using HPE Virtual Lock technology?
Answer : C
Detailed Explanatio n:
Rationale for Correct Answe r:
Option C is correct because HPE StoreOnce Virtual Lock technology provides immutability at the Catalyst store level, preventing backup data from being deleted or modified for a defined retention period. This ensures ransomware or malicious actors cannot encrypt, alter, or delete the protected backups, aligning with modern data protection requirements for immutability and compliance. In integration with Veeam v12, backups stored on StoreOnce Catalyst stores can be locked, creating an additional immutability layer beyond application-consistent snapshots.
Analysis of Incorrect Options (Distractors):
A: Virtual Lock is not a Veeam feature. While Veeam v12 supports immutability on certain storage backends (object lock-enabled S3, hardened Linux repositories), HPE Virtual Lock is specific to StoreOnce Catalyst stores, not Veeam job settings.
B: VMware vCenter datastores do not have a native immutability feature. Snapshots in vCenter can be deleted or corrupted during ransomware events, making this option incorrect.
D: HPE Alletra arrays support application-consistent snapshots and replication, but they do not provide the immutability guarantee that StoreOnce Virtual Lock enforces. Array-level snapshots can still be deleted if admin credentials are compromised.
Key Concept:
This question targets knowledge of HPE StoreOnce Virtual Lock --- a feature designed to enforce immutability on Catalyst backup stores, making backup data resistant to deletion or alteration during ransomware or insider attacks.
HPE StoreOnce Systems Technical White Paper
HPE StoreOnce and Veeam Integration Best Practices
HPE Data Protection Solutions for Ransomware Resilience Guide
Question 7
Select the scenario where implementing FCoE would be an appropriate solution.
Answer : A
Detailed Explanatio n:
Rationale for Correct Answe r:
Option A is correct because Fibre Channel over Ethernet (FCoE) is designed for large enterprise environments that already have Fibre Channel (FC) infrastructures but want to simplify cabling and reduce hardware by converging LAN and SAN traffic over a single Ethernet fabric. FCoE retains the efficiency, low latency, and reliability of Fibre Channel while leveraging Ethernet to minimize physical infrastructure costs. This aligns with HPE's best practices for environments using HPE Alletra 9000/Primera or HPE Nimble arrays connected to converged networks where cost reduction and high performance are equally important.
Analysis of Incorrect Options (Distractors):
B: Real-time replication across WANs requires protocols like HPE 3PAR/Alletra Remote Copy, asynchronous/synchronous replication, or HPE Peer Persistence. FCoE is not suited for high-latency WANs because it is a LAN protocol designed for short distances within a data center.
C: For inter-data center SAN unification, FCIP (Fibre Channel over IP) or iSCSI are more suitable. FCoE does not handle long-distance high-latency links effectively.
D: A startup building AI applications with cloud workloads typically benefits from object storage (HPE Scality RING, HPE GreenLake for File and Object) or direct cloud-native APIs (S3/Blob). FCoE is irrelevant in this use case since it is on-prem and infrastructure-focused.
Key Concept:
The question is testing knowledge of FCoE and its appropriate deployment scenarios --- specifically, its role in consolidating storage and network traffic inside enterprise data centers while preserving Fibre Channel protocol advantages.
HPE Storage Networking Best Practices Guide
HPE Primera/Alletra 9000 Technical White Paper
Fibre Channel over Ethernet Standards Overview (IEEE 802.1Qbb, 802.1Qaz)
 All Official Question Types