Page: 1
/ 14
Total 65 questions
Juniper Data Center, Specialist JN0-481 Exam Questions
Question 1
In Juniper Apstra terminology, to which network operating system concept does a routing zone refer?
Answer : B
In Apstra 5.1, a routing zone is the primary construct used to represent an L3 domain for multitenant isolation. In traditional network operating system terms, that maps to a VRF (Virtual Routing and Forwarding instance). Each routing zone is placed ''in its own VRF,'' which provides independent routing tables and isolates IP traffic so that different tenants can reuse overlapping IP subnets without conflict. This is central to modern EVPN-VXLAN data center design, where tenants typically require clean separation of routing and policy boundaries.
Within a routing zone, you can create one or more virtual networks (often mapped to VXLAN segments) that provide L2 extension across racks while still being contained by the tenant's VRF. If L3 gateway services are enabled for those virtual networks, their gateway interfaces (for example, IRB interfaces on Junos v24.4 leaf switches) are associated with the routing zone's VRF so that inter-subnet routing occurs within the tenant boundary.
This terminology distinction is important: an IRB is an interface construct used to provide L3 gateway functionality for a VLAN/VXLAN segment; a VLAN is a Layer 2 segmentation mechanism; and an access list is a policy enforcement tool. A routing zone, however, defines the tenant's L3 routing context, which is precisely what a VRF provides on Junos.
Verified Juniper sources (URLs):
https://www.juniper.net/documentation/us/en/software/apstra5.0/apstra-user-guide/topics/concept/routing-zones.html
https://www.juniper.net/documentation/us/en/software/apstra4.2/apstra-user-guide/topics/concept/routing-zones.html
Question 2
Referring to the exhibit,
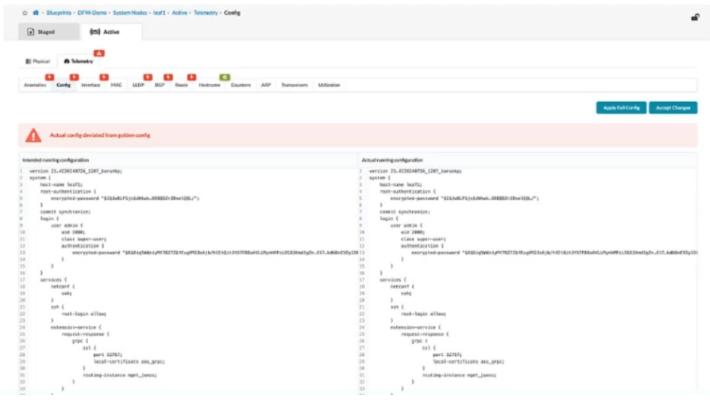
what happens when an operator clicks the Accept Changes button on the right side of the screen in Juniper Apstra?
Answer : B
In Apstra 5.1, this screen represents a configuration deviation workflow: Apstra is comparing the intended (golden) configuration it generated from blueprint intent against the actual configuration currently on the device. When an operator makes a change directly on the switch CLI (for example, on a Junos v24.4 leaf), Apstra detects the difference and flags it as drift because it did not originate from the blueprint's intent model.
Clicking Accept Changes tells Apstra to adopt the device's current CLI state as the new accepted baseline for that device, effectively incorporating the observed CLI delta into Apstra's intended configuration for purposes of future comparison and compliance. In other words, Apstra stops treating that specific deviation as an error because it has been acknowledged and absorbed into the ''golden config'' (the intent-aligned configuration Apstra considers correct for that node). This is commonly used when an emergency change was made on-box and you want Apstra's source of truth to reflect it, rather than reverting it.
This differs from Apply Full Config, which is used to push Apstra's intended configuration down to the device to restore compliance. If you do not accept the change, a later commit/apply action can overwrite the CLI-entered configuration to re-align with blueprint intent.
Question 3
What are three phases of the Juniper Apstra data center life cycle? (Choose three.)
Answer : B, D, E
Juniper Apstra describes data center fabric management as a full lifecycle that spans three core phases: Design (Day 0), Deployment (Day 1), and Operations (Day 2). These phases map directly to how Apstra applies intent-based networking to a data center fabric.
In the Design phase, you model the intended architecture---templates (3-stage or 5-stage), rack types, logical devices, interface maps, resource pools, and high-level constructs such as routing zones and virtual networks. The objective is to capture intent in a vendor-agnostic way while ensuring consistency and validation before anything is pushed.
In the Deployment phase, Apstra turns the modeled intent into device-level implementation. This includes onboarding systems, assigning device profiles, allocating resources, rendering configurations, and pushing the resulting configuration to switches so the IP fabric becomes operational. This is where Junos v24.4 leaf/spine nodes receive underlay and overlay configuration generated from the blueprint.
In the Operational phase, Apstra continuously validates the running network against intent using telemetry and analytics (IBA), detects deviations and anomalies, supports maintenance workflows (such as drain), and provides troubleshooting tools (queries, time-series utilization, and configuration compliance).
''Configuration'' and ''installation'' are activities that occur within the lifecycle, but the lifecycle phases themselves are Design, Deployment, and Operations.
Question 4
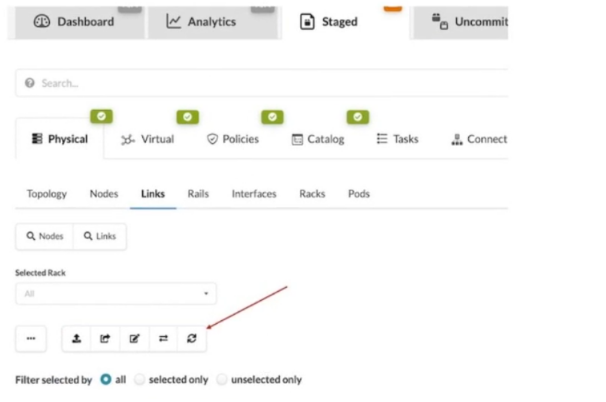
What does clicking the indicated icon shown in the exhibit accomplish?
Answer : B
In Apstra 5.1, the Staged > Physical > Links workspace is where you build and validate the cabling (link) intent for the fabric before committing changes. During deployment and day-0/1 build, Apstra can leverage LLDP neighbor discovery from the connected devices to accelerate and validate the cabling map. The indicated toolbar icon in the Links view is used to fetch discovered LLDP data from the devices so Apstra can compare the discovered neighbor relationships with the intended topology and, depending on workflow, help populate or validate link endpoints.
This is particularly important in leaf-spine IP fabrics because correct physical connectivity underpins the entire underlay---interface states, point-to-point addressing, and BGP sessions. In an EVPN-VXLAN design running Junos v24.4, broken or mis-cabled links quickly manifest as missing underlay adjacencies and failed EVPN control-plane signaling. Pulling LLDP discovery into Apstra helps you identify mismatches early (wrong neighbor, wrong port, missing neighbor) and reduces manual cabling errors.
This action is not merely a UI refresh, it does not wipe the cable map, and it does not modify link speeds. Its operational purpose is to import discovered LLDP neighbor information into the blueprint's physical link view so Apstra can assist with accurate topology validation and deployment readiness.
Question 5
Which three statements are correct about property sets? (Choose three.)
Answer : A, B, E
In Apstra 5.1, property sets are structured data objects (YAML/JSON) used to hold values that templates can consume at render time. Their most common use is with configlets, where property set key/value pairs are referenced as variables inside the template so Apstra can perform variable substitution during configuration generation. This directly supports statement B.
Property sets are also designed to be reusable. A single configlet can reference more than one property set (for example, one set for NTP servers and another for syslog collectors), allowing clean separation of data domains and easier lifecycle updates. This supports statement E.
Operationally, when you bring design content into a blueprint, the blueprint must have the required supporting objects available. In Apstra workflows, configlets that use property sets require those property sets to be present in the blueprint context (commonly accomplished by importing the relevant property set(s) from the catalog into the blueprint as part of bringing in the configlet and its dependencies). This aligns with statement A as the blueprint-level outcome: the property sets used by an imported configlet are imported/available in the blueprint for rendering.
Statements C and D are incorrect because property sets are not limited only to configlets (they are also used with Analytics probes), and the syntax is not vendor-specific---Apstra uses standard YAML/JSON structures independent of NOS.
Verified Juniper sources (URLs):
https://www.juniper.net/documentation/us/en/software/apstra5.1/apstra-user-guide/topics/concept/property-set-datacenter-design.html
https://www.juniper.net/documentation/us/en/software/apstra4.2/apstra-user-guide/topics/concept/property-set-datacenter-design.html
https://www.juniper.net/documentation/us/en/software/apstra5.1/apstra-user-guide/topics/ref/configlet-examples.html
Question 6
An operator is working on a capacity-planning exercise. The operator needs to examine the pre-built time-series information regarding link utilization. In the Juniper Apstra UI, which top-level tab would the operator have to access to find this information?
Answer : C
In Apstra 5.1, capacity planning based on pre-built time-series telemetry (such as link utilization trends) is part of Intent-Based Analytics (IBA). IBA is where Apstra ingests streaming telemetry from fabric devices, stores it as time-series data, and presents it through built-in analytics views (dashboards/widgets) and probes. Because the question specifically calls out ''pre-built time series information regarding link utilization,'' the correct UI location is the Analytics top-level tab within the blueprint.
The Active tab is primarily oriented to operational state and day-2 workflows (for example, viewing live state, queries, and device-level operational views). The Staged tab is where you modify intent (physical/virtual design, policies, catalog items) prior to committing and deploying. The Dashboard provides a high-level blueprint overview and navigation, but the drill-down and time-series analytics views that support trending and capacity analysis are accessed via Analytics.
In an EVPN-VXLAN fabric using Junos v24.4, link utilization time-series is particularly valuable because underlay congestion can degrade overlay performance (BGP convergence behavior, ECMP distribution effectiveness, and endpoint experience). Apstra's Analytics tab centralizes these metrics so operators can evaluate utilization baselines, identify sustained hot links, and support proactive actions (rebalancing, adding capacity, or adjusting design intent) without relying on ad-hoc per-device CLI polling.
Verified Juniper sources (URLs):
https://www.juniper.net/documentation/us/en/software/apstra5.1/apstra-custom-telemetry-collection-guide/topics/concept/apstra-telemetry-and-intent-based-analytics.html
Question 7
Exhibit.
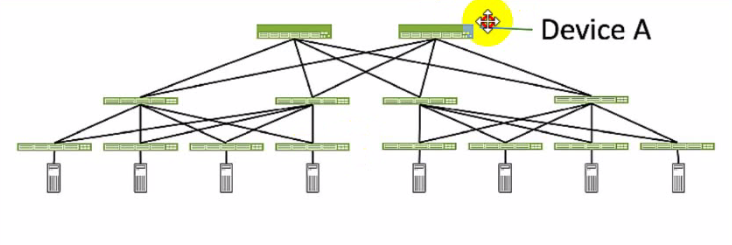
Referring to the exhibit, which role does Device A serve in an IP fabric?
Answer : B
Device A serves as a spine in an IP fabric. An IP fabric is a network architecture that uses a spine-leaf topology to provide high performance, scalability, and reliability for data center networks. A spine-leaf topology consists of two layers of devices: spine devices and leaf devices. Spine devices are the core devices that interconnect all the leaf devices using equal-cost multipath (ECMP) routing. Leaf devices are the edge devices that connect to the servers, storage, or other network devices. In the exhibit, Device A is connected to four leaf devices using multiple links, which indicates that it is a spine device. The other options are incorrect because:
A . leaf is wrong because a leaf device is an edge device that connects to the servers, storage, or other network devices. In the exhibit, Device A is not connected to any servers, storage, or other network devices, but only to four leaf devices, which indicates that it is not a leaf device.
C . super spine is wrong because a super spine device is a higher-level device that interconnects multiple spine devices in a large-scale IP fabric. A super spine device is typically used when the number of leaf devices exceeds the port density of a single spine device. In the exhibit, Device A is not connected to any other spine devices, but only to four leaf devices, which indicates that it is not a super spine device.
D . server is wrong because a server device is a compute or storage device that connects to a leaf device in an IP fabric. A server device is typically the end host that provides or consumes data in the network. In the exhibit, Device A is not connected to any leaf devices, but only to four leaf devices, which indicates that it is not a server device.Reference:
IP Fabric Underlay Network Design and Implementation
IP Fabric Overview
IP Fabric Architecture
 All Official Question Types