Page: 1
/ 14
Total 75 questions
Pure Storage Pure Certified FlashArray Storage Professional FlashArray-Storage-Professional Exam Questions
Question 1
A storage administrator is configuring a new volume and wants to provision 500GB. If the administrator accidentally selects PB, what will happen?
Answer : B
Pure Storage FlashArrays utilize Thin Provisioning as a core, always-on architectural principle. When a volume is created, the 'size' assigned to it is merely a logical limit (a quota) presented to the host; no physical back-end flash capacity is allocated or 'pinned' at the time of creation.
Because of this architecture, Purity allows administrators to create volumes that are significantly larger than the actual physical capacity of the array (this is known as over-provisioning). If an administrator accidentally selects PB (Petabytes) instead of GB, the Purity GUI will allow the volume to be created because it is a logical operation that doesn't immediately consume 1PB of physical flash. However, Purity includes a built-in safety check: if the requested logical size is exceptionally large or exceeds the current physical capacity of the array, the GUI will present a warning or confirmation prompt to ensure the administrator is aware of the massive logical size being provisioned before finalizing the change.
Here is why the other options are incorrect:
The volume will be created and space will immediately be used (A): This describes 'Thick Provisioning,' which Pure Storage does not use. Space is only consumed on a FlashArray when unique data is actually written by the host and processed by the deduplication and compression engines.
The volume will not be created and a warning will be displayed (C): Purity does not strictly forbid over-provisioning. While it warns the user to prevent human error, it does not block the creation of the volume, as over-provisioning is a standard practice in thin-provisioned environments.
Question 2
Pure Protect //DRaaS is configured with a Business Policy to back up data to AWS. An administrator, with DRaaS Global Admin access, is trying to delete the policy but is unable to do so.
What is restricting the administrator from deleting the policy?
Answer : A
In policy-driven data protection and disaster recovery architectures like Pure Protect //DRaaS, a 'Business Policy' dictates the critical Service Level Agreements (SLAs) for your environment, such as your Recovery Point Objective (RPO), replication frequency, and retention schedules. These policies are then assigned to 'Application Groups,' which act as logical containers for the specific virtual machines being protected and replicated to AWS.
As a fundamental safety mechanism built into the platform to prevent accidental exposure and SLA breaches, the system places a hard dependency lock on actively used policies. An administrator cannot delete a Business Policy if there are still Application Groups actively relying on it for their DR scheduling. To successfully delete the policy, the administrator must first modify all associated Application Groups and assign them to a different Business Policy, or completely remove the protection from those groups.
Here is why the other options are incorrect:
The administrator also needs DRaaS Cloud Admin access (C): The scenario explicitly states the user already has 'DRaaS Global Admin access.' In the Pure Protect //DRaaS Role-Based Access Control (RBAC) model, Global Admin is the highest tier of privilege and has full rights to manage and delete policies. A lack of permissions is not the issue here.
The Business Policy is marked as the Primary Policy (B): While a policy might be a default or primary template, the actual hard restriction that prevents deletion in the software is active resource assignment (the Application Groups), not just a 'Primary' label.
Question 3
What is the proper procedure for stopping asynchronous replication and in-progress transfers?
Answer : C
According to the official Pure Storage FlashArray Asynchronous Replication Configuration and Best Practices Guide, the proper and immediate method to halt an active, in-progress asynchronous replication transfer is by disallowing the protection group at the target.
When you navigate to the target FlashArray and disallow the specific Protection Group, Purity immediately breaks the replication authorization for that group. If there is an in-progress snapshot transfer occurring at that exact moment, the transfer is immediately stopped, and the partially transferred snapshot data is discarded on the target side.
Here is why the other options are incorrect:
Disabling the replication schedule (B): Toggling the replication schedule to 'Disabled' only prevents future scheduled snapshots from being created and sent. It does not kill or interrupt a replication transfer that is already currently in progress.
Removing the volume member from a protection group (A): Modifying the members of a protection group updates the configuration for the next snapshot cycle. It does not actively abort the transmission of the current point-in-time snapshot that the array is already busy sending over the WAN.
Question 4
An administrator is setting up FA File using the FlashArray GUI. The company is an NFS only shop and needs to configure their remote user authentication.
Which of the following GUI locations should the administrator use to configure access?
Answer : B
For FlashArray File Services (FA File), user authentication and mapping depend on the storage protocol being used. In an NFS-only environment, remote user authentication (resolving UNIX UIDs and GIDs to actual usernames and managing access) is typically handled via LDAP or NIS.
To configure this integration in the Purity GUI, the storage administrator must navigate to Settings > Access > Directory Services. This specific section allows the FlashArray to connect to a centralized directory server (such as OpenLDAP or even Active Directory providing LDAP services) to pull the necessary UNIX user and group attributes required for NFS file permissions to function properly.
Here is why the other options are incorrect:
Settings > Access > Create Active Directory Account (A): This specific menu path is used strictly for configuring native Active Directory (AD) computer accounts and joining the domain to support the SMB (Server Message Block) protocol. Since the scenario explicitly states the company is an 'NFS only shop,' configuring an SMB AD account is not the correct step.
Settings > Access > File System (C): While you manage file-level exports and policies within the Purity file interface, the global configuration for remote user authentication and directory server integration lives under the dedicated Directory Services pane.
Question 5
RFC2307 enables cross-protocol support for which two protocols?
Answer : C
Understanding RFC2307: RFC2307 is an extension to the LDAP (Lightweight Directory Access Protocol) schema that allows for the storage of Unix-style information (POSIX attributes) within a directory service, most commonly Microsoft Active Directory. These attributes include things like uidNumber (User ID), gidNumber (Group ID), and login shells.
The Cross-Protocol Challenge: In a Unified Storage environment where the same data needs to be accessed by both Windows clients (using the SMB protocol) and Linux/Unix clients (using the NFS protocol), the storage array must be able to map a Windows Security Identifier (SID) to a Unix UID/GID.
How Pure Uses It: When an administrator enables RFC2307 support in Purity//FA File Services, the FlashArray can query Active Directory to retrieve these POSIX attributes. This creates a 1:1 mapping between the Windows user and the Unix identity.
The Benefit: This mapping ensures that a user can create a file via SMB and another user (or the same user on a different system) can access or modify that same file via NFS while maintaining consistent permission enforcement and ownership records. Without this (or a similar mapping service like NIS or local files), cross-protocol access often results in permission 'Mapping' errors or files being owned by 'nobody.'
Question 6
During a test failover using ActiveDR, what content will be presented to the target pod?
Answer : C
ActiveDR is Pure Storage's continuous, near-sync replication solution. It differs fundamentally from standard asynchronous replication because it uses a continuous stream of data rather than snapshot-based 'periodic refreshes' (which eliminates Option A).
When you perform a test failover in ActiveDR, you do so by promoting the target pod. The target pod becomes writable, allowing your hosts and applications to run against the replicated data without disrupting the ongoing continuous replication from the source array in the background.
When the test is completed, you demote the target pod. To ensure that the data generated during your test failover isn't accidentally lost forever, ActiveDR automatically creates an undo pod at the exact moment of demotion.
If you need to resume that exact test failover scenario or recover the test data, you can re-promote the target pod and instruct ActiveDR to present the content from the undo pod. This unique mechanism allows storage administrators to seamlessly non-disruptively test, pause, and resume DR environments without affecting production protection.
Question 7
Refer to the exhibit:
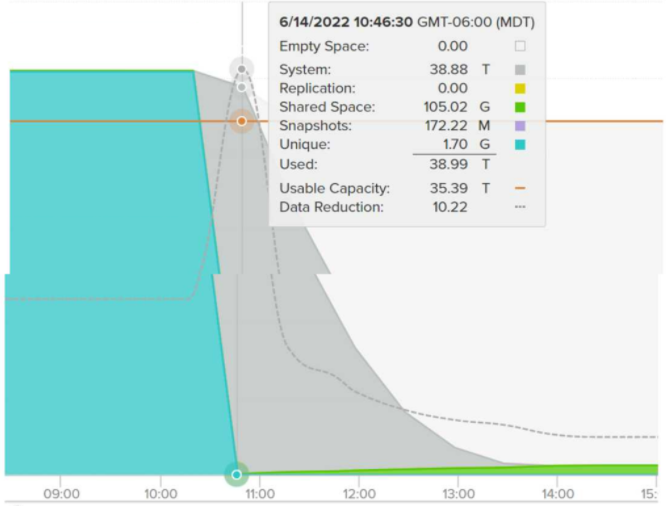
What is the most likely cause of system space in this capacity graph?
Answer : B
Analyzing the Graph: The provided capacity graph shows a sharp, vertical drop in Unique and Shared space (the teal/green sections) at approximately 10:45. Simultaneously, there is a massive spike in System space (the grey shaded area).
The 'System' Space Spike: In Purity, when a volume is deleted and eradicated, the data isn't physically wiped from the flash modules instantly. Instead, the logical references are removed, and the blocks are moved into a 'Pending Reclamation' state. In older versions of Purity reporting (or specific views), this pending work is often categorized under System space until the background Garbage Collection (GC) process can physically reclaim it.
The Decay Curve: Notice the grey 'System' area gradually tapers down over the following hours (from 11:00 to 14:00). This is the visual representation of the array's Garbage Collection engine working in the background to physically free up those blocks.
Why Option C is incorrect: If SafeMode were enabled, the space would not move into 'System' space in this manner; it would remain locked in the Snapshots or Destroyed bucket for the duration of the retention period, preventing the graph from dropping at all.
Why Option A is incorrect: If space reclamation stopped working, the grey 'System' area would stay flat and would not decay over time. The fact that it is trending downward proves that reclamation is actively processing the deleted volume.
 All Official Question Types