Page: 1
/ 14
Total 152 questions
Salesforce Certified MuleSoft Platform Architect (Mule-Arch-201) Exam Questions
Question 1
A large organization with an experienced central IT department is getting started using MuleSoft. There is a project to connect a siloed back-end system to a new
Customer Relationship Management (CRM) system. The Center for Enablement is coaching them to use API-led connectivity.
What action would support the creation of an application network using API-led connectivity?
Answer : D
For an organization starting with API-led connectivity to integrate a siloed back-end system with a new CRM, the following approach aligns with best practices and MuleSoft's Center for Enablement (C4E) guidance:
API-led Connectivity: This model organizes APIs into distinct layers (System, Process, and Experience) to improve reusability, modularity, and manageability.
System APIs are used to expose and unlock data from core systems (such as back-end applications or databases).
Process APIs orchestrate data across multiple systems and transform it as needed.
Experience APIs format the data specifically for consumption by applications or devices, such as the CRM in this case.
Step to Support Application Network:
Create a System API for the back-end system. This API should expose the necessary data to support integration with the CRM.
By creating a System API with a RESTful interface, data can be accessed in a standardized way, making it easier to integrate with other systems and supporting future scalability.
Why Option D is Correct:
Creating a System API aligns with the principle of API-led connectivity, ensuring that data is exposed in a reusable manner. This API can then be orchestrated by Process APIs as needed to meet CRM requirements and can easily be extended to other applications.
of Incorrect Options:
Option A (creating a business process model) does not directly enable connectivity or expose back-end data through APIs.
Option B is unnecessary at this stage; assessing CRM capabilities like OAuth 2.0 support is not directly related to creating the application network via System APIs.
Option C contradicts API-led best practices by suggesting a point-to-point integration, which API-led connectivity seeks to avoid due to its lack of flexibility and scalability.
Reference Refer to MuleSoft's API-led Connectivity resources for a detailed framework on building scalable integration layers using System, Process, and Experience APIs.
Question 2
To minimize operation costs, a customer wants to use a CloudHub 1.0 solution. The customer's requirements are:
* Separate resources with two Business groups
* High-availability (HA) for all APIs
* Route traffic via Dedicated load balancer (DLBs)
* Separate environments into production and non-production
Which solution meets the customer's needs?
Answer : B
Understanding the Requirements:
Business Groups: The solution must support two business groups, which typically require separate VPCs for logical separation.
High Availability (HA): Requires deploying resources across multiple availability zones.
Dedicated Load Balancer (DLB): Traffic should be routed via DLBs, which operate within VPCs on CloudHub.
Separate Environments: There needs to be separation between production and non-production environments.
Evaluating the Options:
Option A: Using a single production and non-production VPC and differentiating business groups via availability zones is not ideal as it does not provide full separation for each business group, and using maximum CIDR allocation is wasteful.
Option B (Correct Answer): Creating separate production and non-production VPCs per business group with minimized CIDR blocks, multiple availability zones, and multiple workers per application for HA meets all requirements effectively.
Option C: While this option separates VPCs per business group, it does not fully address the requirement for HA across availability zones by specifying multi-zone deployment only during API deployment, which may not guarantee redundancy.
Option D: Configuring subnets to differentiate business groups within a single production and non-production VPC does not fully separate the business groups, which is a requirement.
Conclusion:
Option B is the best choice as it meets the requirements for high availability, business group separation, and cost efficiency by using minimized CIDR allocations and deploying multiple workers across availability zones.
For further reference, refer to MuleSoft's documentation on VPC configuration and high availability deployment strategies.
Question 3
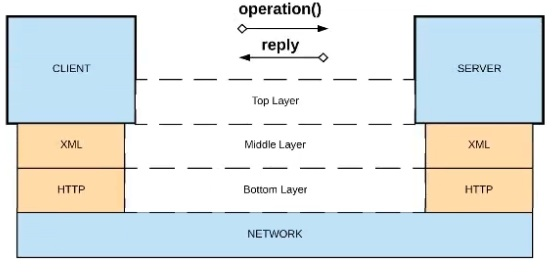
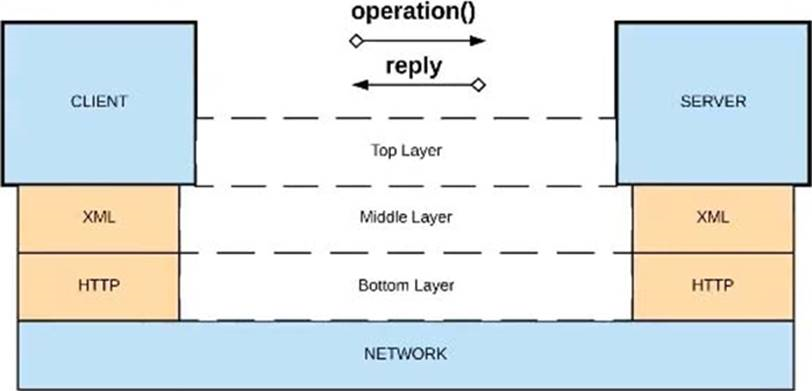
Refer to the exhibit.
What is a valid API in the sense of API-led connectivity and application networks?
A) Java RMI over TCP
B) Java RMI over TCP
C) CORBA over HOP
D) XML over UDP
Answer : D
Correct Answe r:XML over HTTP
*****************************************
>>API-led connectivity and Application Networks urge to have the APIs on HTTP based protocols for building most effective APIs and networks on top of them.
>>The HTTP based APIs allow the platform to apply various varities of policies to address many NFRs
>>The HTTP based APIs also allow to implement many standard and effective implementation patterns that adhere to HTTP based w3c rules.
Bottom of Form
Top of Form
Question 4
What should be ensured before sharing an API through a public Anypoint Exchange portal?
Answer : A
Correct Answe r: The visibility level of the API instances of that API that need to be publicly accessible should be set to public visibility.
*****************************************
https://docs.mulesoft.com/exchange/to-share-api-asset-to-portal
Question 5
A European company has customers all across Europe, and the IT department is migrating from an older platform to MuleSoft. The main requirements are that the
new platform should allow redeployments with zero downtime and deployment of applications to multiple runtime versions, provide security and speed, and utilize Anypoint MQ
as the message service.
Which runtime plane should the company select based on the requirements without additional network configuration?
Answer : C
For a European company with requirements such as zero-downtime redeployment, deployment to multiple runtime versions, secure and fast performance, and the use of Anypoint MQ without additional network configuration, CloudHub is the best choice for the following reasons:
Zero-Downtime Redeployment: CloudHub supports zero-downtime deployment, which allows seamless redeployment of applications without impacting availability.
Support for Multiple Runtime Versions: CloudHub allows deploying applications across different Mule runtime versions, giving flexibility to test and migrate applications as needed.
Integrated Anypoint MQ: Anypoint MQ, which is fully integrated with CloudHub, provides reliable messaging across applications. Choosing CloudHub removes the need for additional network configurations, as Anypoint MQ can be directly accessed in this hosted environment.
Security and Performance: CloudHub offers secure networking, automatic scaling, and optimized performance without requiring a complex setup. This is managed by MuleSoft's infrastructure, meeting the speed and security requirements with minimal overhead.
of Incorrect Options:
Option A and D (Runtime Fabric on VMs or Self-Managed Kubernetes): While Runtime Fabric offers flexibility, it requires more complex network and infrastructure configurations, which is not ideal if the company seeks simplicity.
Option B (Customer-hosted): This would require additional network and security configuration, which does not align with the requirement of minimizing setup complexity.
Reference For more information on CloudHub's capabilities regarding zero-downtime deployments and integration with Anypoint MQ, refer to MuleSoft documentation on CloudHub.
Question 6
What do the API invocation metrics provided by Anypoint Platform provide?
Answer : C
Correct Answe r: Data on past API invocations to help identify anomalies and usage patterns across various APIs
*****************************************
API Invocation metrics provided by Anypoint Platform:
>> Does NOT provide any Return Of Investment (ROI) related information. So the option suggesting it is OUT.
>> Does NOT provide any information w.r.t how APIs are reused, whether there is effective usage of APIs or not etc...
>> Does NOT prodive any prediction information as such to help us proactively identify any future policy violations.
So, the kind of data/information we can get from such metrics is on past API invocations to help identify anomalies and usage patterns across various APIs.
Question 7
A new upstream API Is being designed to offer an SLA of 500 ms median and 800 ms maximum (99th percentile) response time. The corresponding API implementation needs to sequentially invoke 3 downstream APIs of very similar complexity.
The first of these downstream APIs offers the following SLA for its response time: median: 100 ms, 80th percentile: 500 ms, 95th percentile: 1000 ms.
If possible, how can a timeout be set in the upstream API for the invocation of the first downstream API to meet the new upstream API's desired SLA?
Answer : B
Correct Answe r: Set a timeout of 100ms; that leaves 400ms for other two downstream APIs to complete
*****************************************
Key details to take from the given scenario:
>> Upstream API's designed SLA is 500ms (median). Lets ignore maximum SLA response times.
>> This API calls 3 downstream APIs sequentially and all these are of similar complexity.
>> The first downstream API is offering median SLA of 100ms, 80th percentile: 500ms; 95th percentile: 1000ms.
Based on the above details:
>> We can rule out the option which is suggesting to set 50ms timeout. Because, if the median SLA itself being offered is 100ms then most of the calls are going to timeout and time gets wasted in retried them and eventually gets exhausted with all retries. Even if some retries gets successful, the remaining time wont leave enough room for 2nd and 3rd downstream APIs to respond within time.
>> The option suggesting to NOT set a timeout as the invocation of this API is mandatory and so we must wait until it responds is silly. As not setting time out would go against the good implementation pattern and moreover if the first API is not responding within its offered median SLA 100ms then most probably it would either respond in 500ms (80th percentile) or 1000ms (95th percentile). In BOTH cases, getting a successful response from 1st downstream API does NO GOOD because already by this time the Upstream API SLA of 500 ms is breached. There is no time left to call 2nd and 3rd downstream APIs.
>> It is NOT true that no timeout is possible to meet the upstream APIs desired SLA.
As 1st downstream API is offering its median SLA of 100ms, it means MOST of the time we would get the responses within that time. So, setting a timeout of 100ms would be ideal for MOST calls as it leaves enough room of 400ms for remaining 2 downstream API calls.
 All Official Question Types